AcciSAGE
Spatio-Temporal Accident Grounding in Surveillance Videos via Error-Aware VLM Tuning
Error-aware vision-language model tuning for temporal, spatial, and collision-type grounding in surveillance accident videos.
Research introduction video
A research introduction showing global-to-local accident grounding, task-specific LoRA adapters, SAPO refinement, and accident case demonstrations.
Abstract
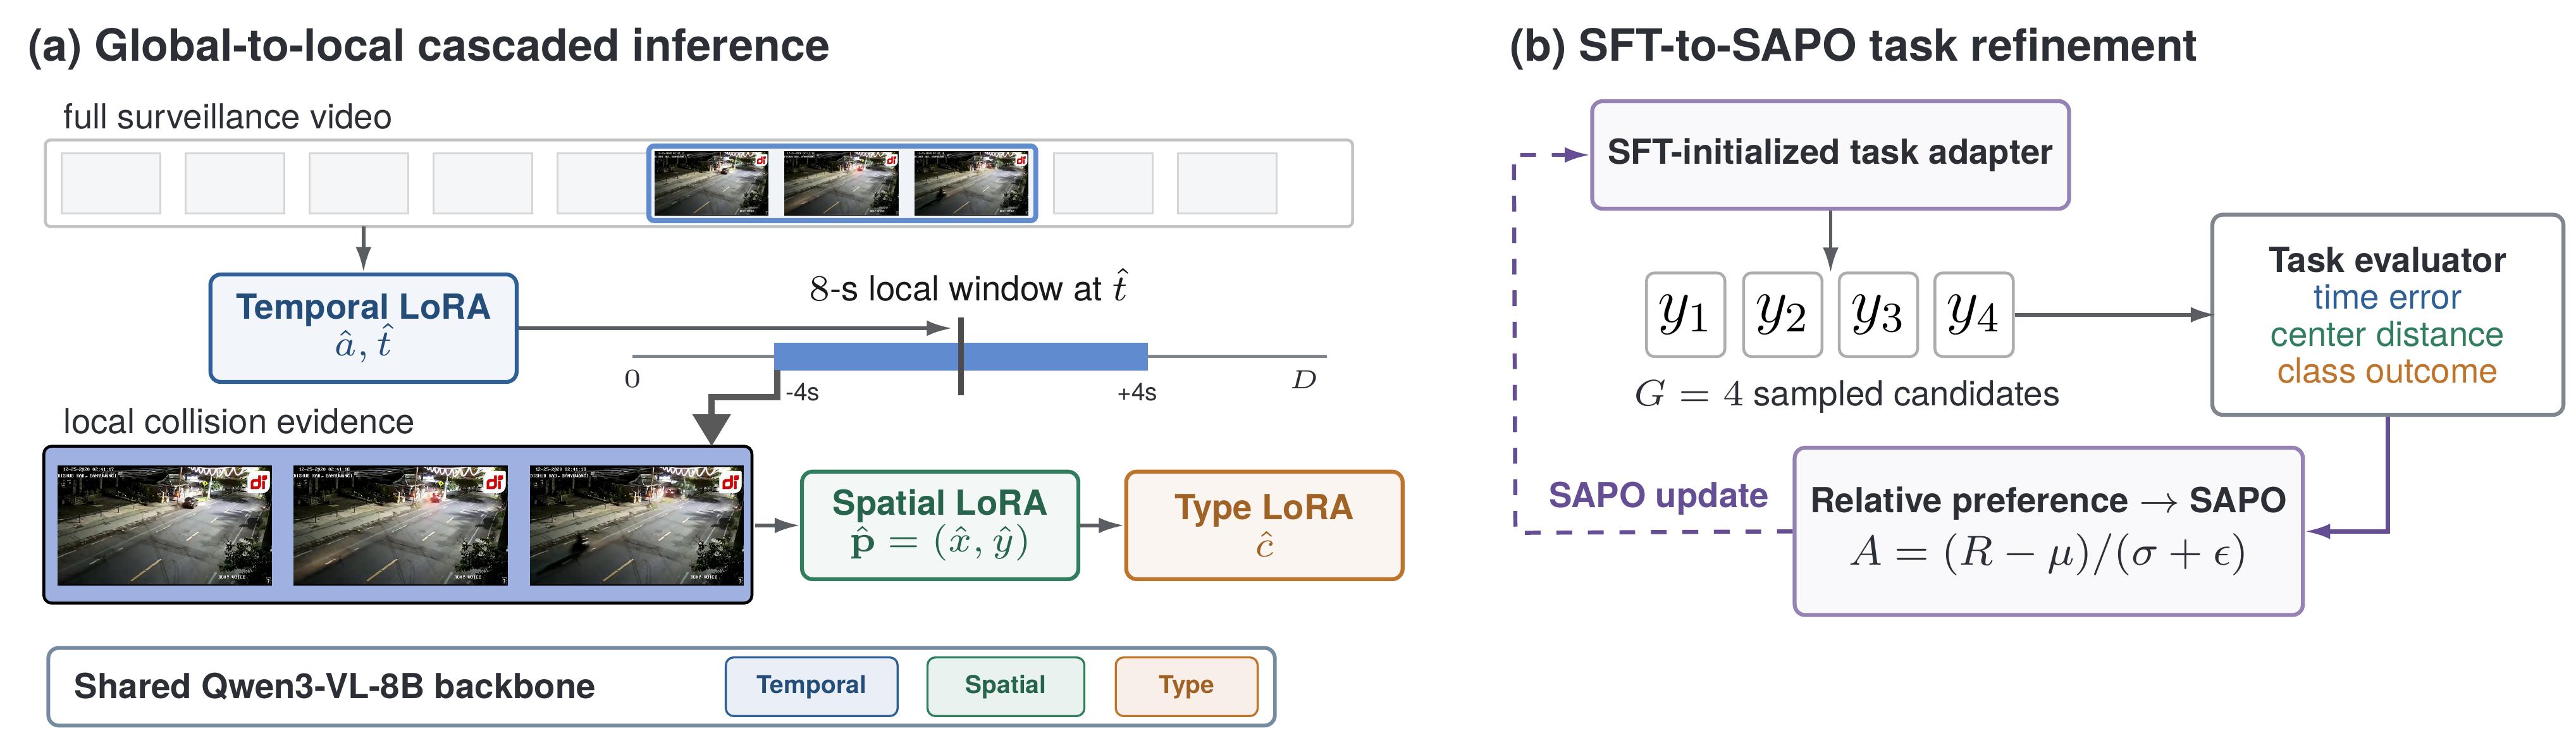
AcciSAGE is a global-to-local framework for spatio-temporal accident grounding in surveillance videos. It uses one open-weight vision-language backbone with task-specific LoRA adapters for temporal, spatial, and collision-type predictions. Supervised fine-tuning (SFT) is followed by error-aware SAPO refinement with task-aligned rewards.
Method
- Temporal: Ground the accident moment from the full video.
- Spatial: Estimate the accident center in a localized video context.
- Type: Predict the collision category.
Results
Reference results from the public repository on the ACCIDENT IID test set. T₁ is the Gaussian temporal grounding score at σ = 1 second; S is the spatial score, C is collision-type accuracy, and ACCS is their harmonic mean.
| Metric | SFT-only | AcciSAGE (SAPO) |
|---|---|---|
| T₁ | 0.5563 | 0.5672 |
| S | 0.5236 | 0.5352 |
| C | 0.5382 | 0.5493 |
| ACCS | 0.5390 | 0.5503 |
Research status and thesis record
Master’s research, 2026. Manuscript with a public reference implementation.
Master’s thesis: Spatio-Temporal Traffic Accident Grounding in Surveillance Videos via Error-Aware VLM Tuning. National Taipei University of Technology, 2026. Record in Taiwan’s National Digital Library of Theses and Dissertations.
Links
[Master’s thesis] [Source code]
Contact: cjz89k@gmail.com